anvi-report-inversions
Table of Contents
- Authors
- Requires
- Provides
- Usage
- Anvi’o philosophy to find inversions
- Before you run this program
- Other essential inputs to run this program
- Identifying regions of interest
- Finding palindromes
- Confirming inversions
- Computing inversion activity
- Computing inversion activity using previously computed inversions
- Reporting genomic context around inversions
- Searching for conserved motifs in inverted-repeats
- Targeted search
- HTML output
- Other outputs
- Command line interface
- Additional Resources
Reports inversions.
🔙 To the main page of anvi’o programs and artifacts.
Authors
Requires
Provides
Usage
This program allows you to find genomic inversions using metagenomic read recruitment results, and their activity patterns across samples.
Specifically, this program search for site-specific inversions which are carried out by site-specific recombinases. This enzyme recognizes a pair of inverted repeats (IRs). The IRs are distant from each other and the site-specific recombinase invert the DNA fragment between the IRs.
In brief, anvi’o leverages paired-read orientation (through the --fetch-filter mechanism in anvi-profile explained below) to locate regions of interest in a set of contigs. It screens for IRs within regions that are enriched in read pairs that are enriched in forward/forward or reverse/reverse orientations, and uses short-reads to confirm which IRs correspond to real inversions. Anvi’o can also compute the ‘inversion activity’, i.e., the relative proportion of each orientation of an inversion in each sample.
Anvi’o philosophy to find inversions
Much like a T-Rex, the vision of anvi’o relies on movement and it cannot see an inversion if it does not move, or in this case, invert. So let’s start with what you cannot do with this command: you cannot find inversions in a set of contigs alone.
To find an inversion, you need to have short-reads from at least one sample. If there is even a small fraction of the members of a microbial population that have an inverted sequence, then anvi-report-inversions will very likely find it for you!
Before you run this program
Anvi’o is able to locate inversions using the paired-end read orientation. Regular paired-end reads are facing inward with a FWD/REV orientation, but when an inversion happens, some reads will be mapping in the opposite orientation regarding the reference. As a consequence, some paired-end reads will have the same orientation: FWD/FWD or REV/REV.
To leverage that information, anvi’o can profile bam files for FWD/FWD and REV/REV reads only with anvi-profile to make special single-profile-db.
anvi-profile -i bam-file \ -c contigs-db \ --fetch-filter inversion
Other essential inputs to run this program
The main input for anvi-report-inversions is a bams-and-profiles-txt, which is a TAB-delimited file composed of at least four columns:
- Sample name,
- contigs-db,
- single-profile-db generated with the inversion fetch filter,
- bam-file.
If you are interested in also characterizing inversion activity statistics across samples, you will also need to add two more columns into the bams-and-profiles-txt file to point out the paths for the R1 and R2 FASTQ files.
Here is a standard run with default parameters:
anvi-report-inversion -P bams-and-profiles-txt \ -o inversions_output
Identifying regions of interest
While anvi’o could directly search for inverted repeats in all the contigs, it would be a waste of time as many IRs are actually not related to inversions. Instead, anvi’o uses the FWD/FWD and REV/REV reads to identify regions of interest and constrain the search for IRs only in these regions.
For this step, you can set the minimum coverage of FWD/FWD and REV/REV reads to define ‘stretches’ with --min-coverage-to-define-stretches. Lower threshold yield more stretches, but also more noise.
The parameter --min-stretch-length defines the minimum length for a stretch to be considered.
FWD/FWD reads are found on the leftmost side of an inversion, while the REV/REV reads are found on the right side. When an inversion is quite long, a region of low to no coverage can separate the two groups of reads. With the flag --min-distance-between-independent-stretches, anvi’o merges fragmented stretches if they are closer than this value.
When the coverage is quite low, a stretch can be a little bit too short and miss potential IRs, so you use --num-nts-to-pad-a-stretch to extend the stretch by x bp upstream and downstream.
Here are the default values for these flags:
anvi-report-inversions -P bams-and-profiles-txt \ -o inversions_output \ --min-coverage-to-define-stretches 10 \ --min-stretch-length 50 \ --min-distance-between-independent-stretches 2000 \ --num-nts-to-pad-a-stretch 100
Finding palindromes
There are a few parameters to constrain the search for palindromic sequences of the IRs, like a minimum length that can be set with --min-palindrome-length, and a maximum number of mismatches with --max-num-mismatches.
You can set the minimum distance between two palindromic sequences with --min-distance. A distance of 0 would correspond to an in-place palindrome, though they don’t relate to genomic inversions.
When searching for palindromes with mismatches, the algorithm will extend the palindrome length as much as possible, often including mismatches which are outside of the true palindrome sequences. The flag --min-mismatch-distance-to-first-base allows you to trim the palindrome when one or more mismatches are n nucleotides away from a palindrome’s start or stop. The default value is 1, meaning that a palindrome MMMMMM(X)M, where M denotes matching nucleotides and X a mismatch, will be trimmed to the first 6 matches MMMMMM.
There are currently two algorithms to find palindromes in anvi’o: numba and BLAST. Numba is very fast when looking for palindromes in short sequences, and BLAST is more efficient for longer stretches. Anvi’o dynamically set the algorithm according to each stretch length: numba for stretches under 5,000 bp and BLAST for longer stretches. You can use the flag --palindrome-search-algorithm to ask anvi’o to use either of these methods explicitly. Note that results between the two methods may differ.
anvi-report-inversions -P bams-and-profiles-txt \ -o inversions_output \ --min-palindrome-length 10 \ --max-num-mismatches 1 \ --min-distance 50 \ --min-mismatch-distance-to-first-base 1 \ --palindrome-search-algorithm numba
Confirming inversions
Multiple palindromes are usually reported for each stretch and to confirm which one actually relates to an inversions, anvi’o searches short-reads in the bam file for unique constructs that can only occur when a genomic region inverted.
By default, anvi’o reports the first confirmed palindrome and moves to the next stretch. This process is very efficient as a stretch usually has only one inversion. But in rare cases, you can have multiple inversions happening in a single stretch. Then, you can use the flag --check-all-palindromes and anvi’o will look for inversion evidence in the short-reads for every palindrome in a stretch.
Anvi’o looks for inversion evidence in the FWD/FWD and REV/REV reads first. If no evidence is found, then it searches the rest of the reads mapping to the region of interest. If you want to only search the FWD/FWD and REV/REV reads you can use the flag --process-only-inverted-reads
Computing inversion activity
If you provide the short-reads R1 and R2 in the bams-and-profiles-txt, anvi’o can compute the proportion of the inversion’s orientation in each sample.
This is a very time consuming step, and if you have multiple sample, you can use the parameter --num-threads to set the maximum of threads for multithreading when possible.
To compute the inversion’s ratios, anvi’o designs in silico primers based on the palindrome sequence and the upstream/downstream genomic context to search short-reads in the raw fastq files. The variable --oligo-primer-base-length is used to control how much of the palindrome should be used to design the primers. The longer, the more specific, but if it is too long, fewer reads will match to the primer.
This step is very computationally intense, but you can test it with the parameter --end-primer-search-after-x-hits. Once the total number of reads reach this parameter, anvi’o will stop searching further and will continue with the next sample. This flag is only good for testing.
If you want to skip this step, you can use the flag --skip-compute-inversion-activity.
An example command with 12 threads:
anvi-report-inversions -P bams-and-profiles-txt \ -o inversions_output \ --num-threads 12 \ --oligo-primer-base-length 12
Computing inversion activity using previously computed inversions
It is possible to instruct anvi’o to use previously reported inversions to characterize their activity across a larger set of samples. This is possible by passing the program anvi-report-inversions the output file for consensus inversions (i.e., ‘CONSENSUS-INVERSIONS.txt’) or the output file for sample-specific inversions (i.e., ‘INVERSIONS-IN-[SAMPLE-NAME].txt’) from a previous run using the flag --pre-computed-inversions:
anvi-report-inversions -P bams-and-profiles-txt \ --pre-computed-inversions inversions_output/INVERSIONS-CONSENSUS.txt -o activity_calculations
In this mode, anvi-report-inversions will not recalculate inversions, and only report the activity of inversions found in the input file across samples listed in the bams-and-profiles-txt file.
If you have additional samples to make sense of the inversions you already know about, you obviously don’t need to do any additional mapping and profiling. All you need is the contigs-db with which you used to generate the inversion report you already have (i.e., not for the new samples you have), and the r1 and r2 files for the new samples. This is similar to the structure of bams-and-profiles-txt, except the profile_db_path and bam_file_path columns. While the entire purpose of this file is ot have these columns, in this particular instance, when you use the flag --pre-computed-inversions with anvi-report-inversions, ANVI’O SANITY CHECKS WILL NOT REQUIRE THE FILE TO INCLUDE PROFILE-DB AND BAM FILE PATHS. Which will make your life much more easier to scale your search. Which means for this particular application, you can create your bams-and-profiles-txt file only with the columns and you’d still be OK: name, contigs_db_path, r1, r2.
Reporting genomic context around inversions
For every inversion, anvi’o can report the surrounding genes and their function as additional files.
You can use the flag --num-genes-to-consider-in-context to choose how many genes to consider upstream/downstream of the inversion. By default, anvi’o report three genes downstream, and three genes upstream.
To select a specific gene caller, you can use --gene-caller. The default is pyrodigal-gv.
If you want to skip this step, you can use the flag --skip-recovering-genomic-context.
Searching for conserved motifs in inverted-repeats
The inversions are carried out by site-specific recombinase which recognize a DNA motifs on each end of the invertible DNA fragment. This DNA motif is a relatively conserved palindrome separated by a short sequence called a spacer.
A fascinating aspect of site-specific recombinases is that they can invert multiple site, providing the DNA recognition motif is present. Some genomes can have one site-specific recombinase responsible many inversions! Some genomes have a few site-specific recombinase regulating different set of inversions.
When you use this command, anvi’o will leverage the program MEME to identify palindrome motifs in the inverted-repeats. It is done in two steps:
- Per inversion. Anvi’o searches and report three motifs. You can find the output of MEME in each inversion’s directory (e.g.
PER_INV/INV_0001/MEME). - For all inversions. Anvi’o searches for shared and conserved motifs across all inversions. By default it will search for as many motifs as there are inversions. This can be time consuming if you have a lot of inversions, and you can use the flag
--num-of-motifsto specify the number of motifs to be reported. The output of MEME can be found here:PER_INV/ALL_INVERSIONS/MEME.
In the final outputs, we report the ‘motif group’ for each inversions. Which means that you can link together groups of inversion putatively associated with the same site-specific recombinase.
If you want to skip this step, you can use the flag --skip-search-for-motifs.
Targeted search
If you are interested in a given contig region you can use the following flags to limit the search:
--target-contig: contig of interest,--target-region-start: the start position of the region of interest,--target-region-end: the end position of the region of interest.
HTML output
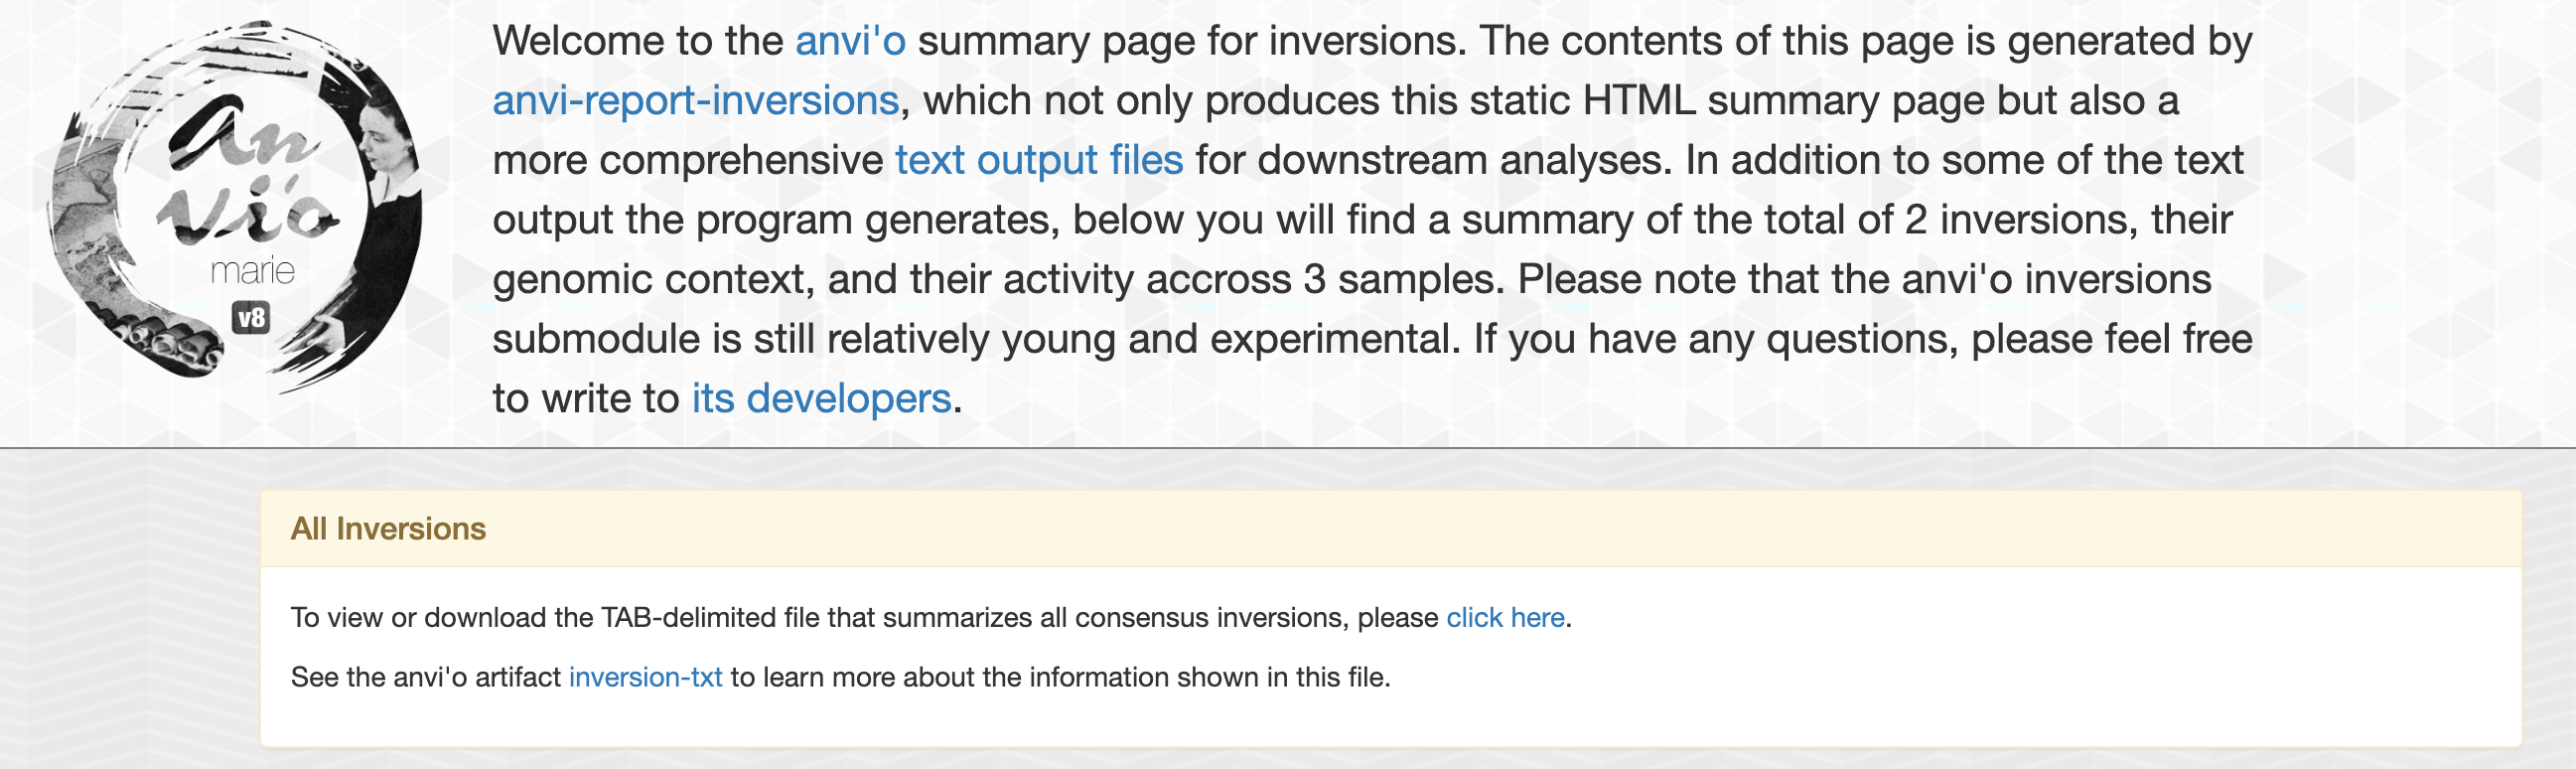
The first output of interest is index.html which is a static html page with all the information about each inversions.
On the top of this page, you will find general informations such as number of inversions found and link to some tab-delimited files that summarize all inversions:
Genomic context
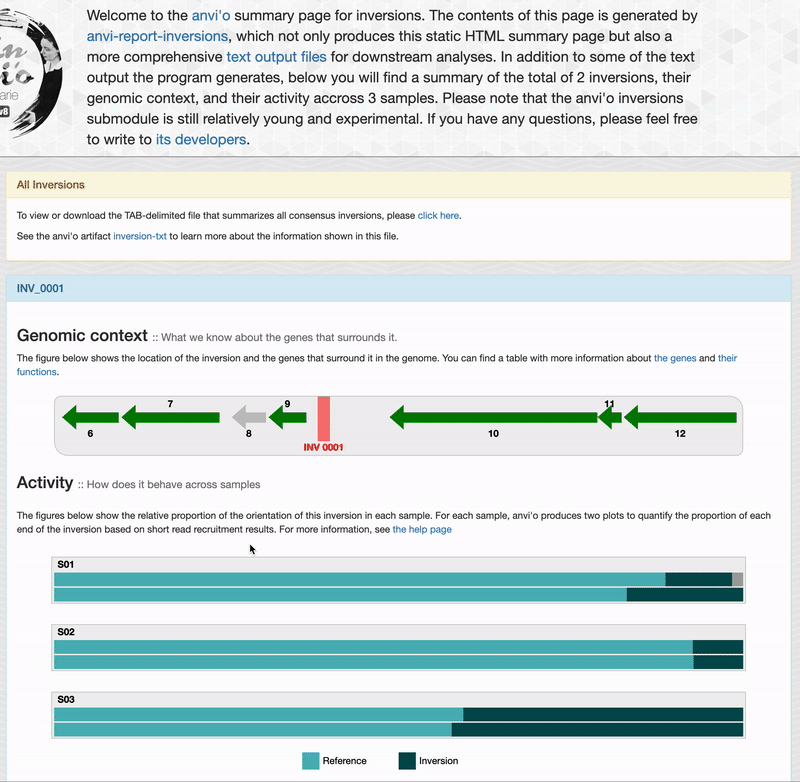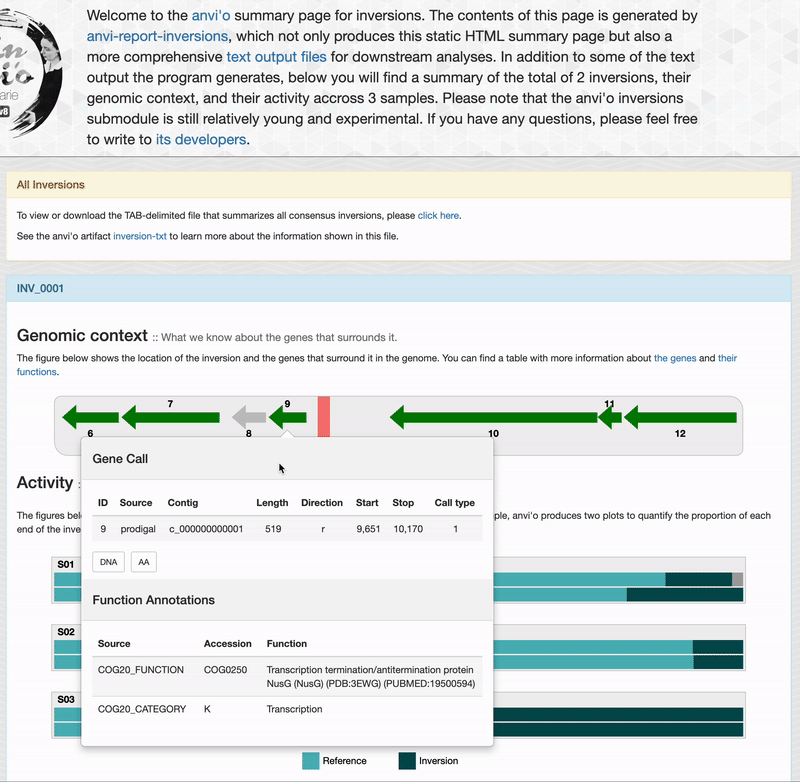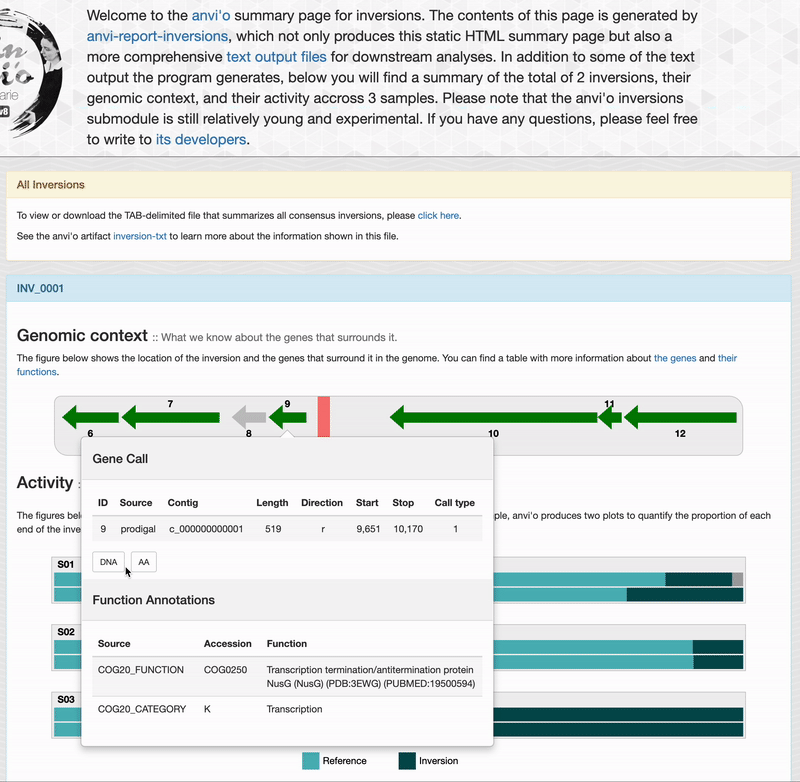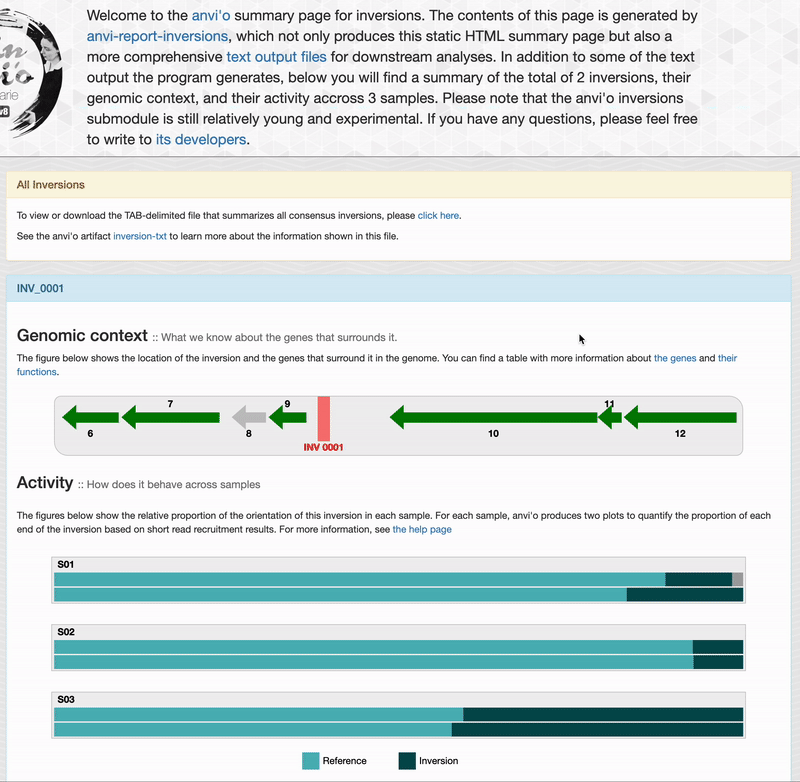
For each inversions you can see the genomic context. This part is interactive and allow you to inspect genes information such as their functions, DNA and amino acid sequences:
Activity
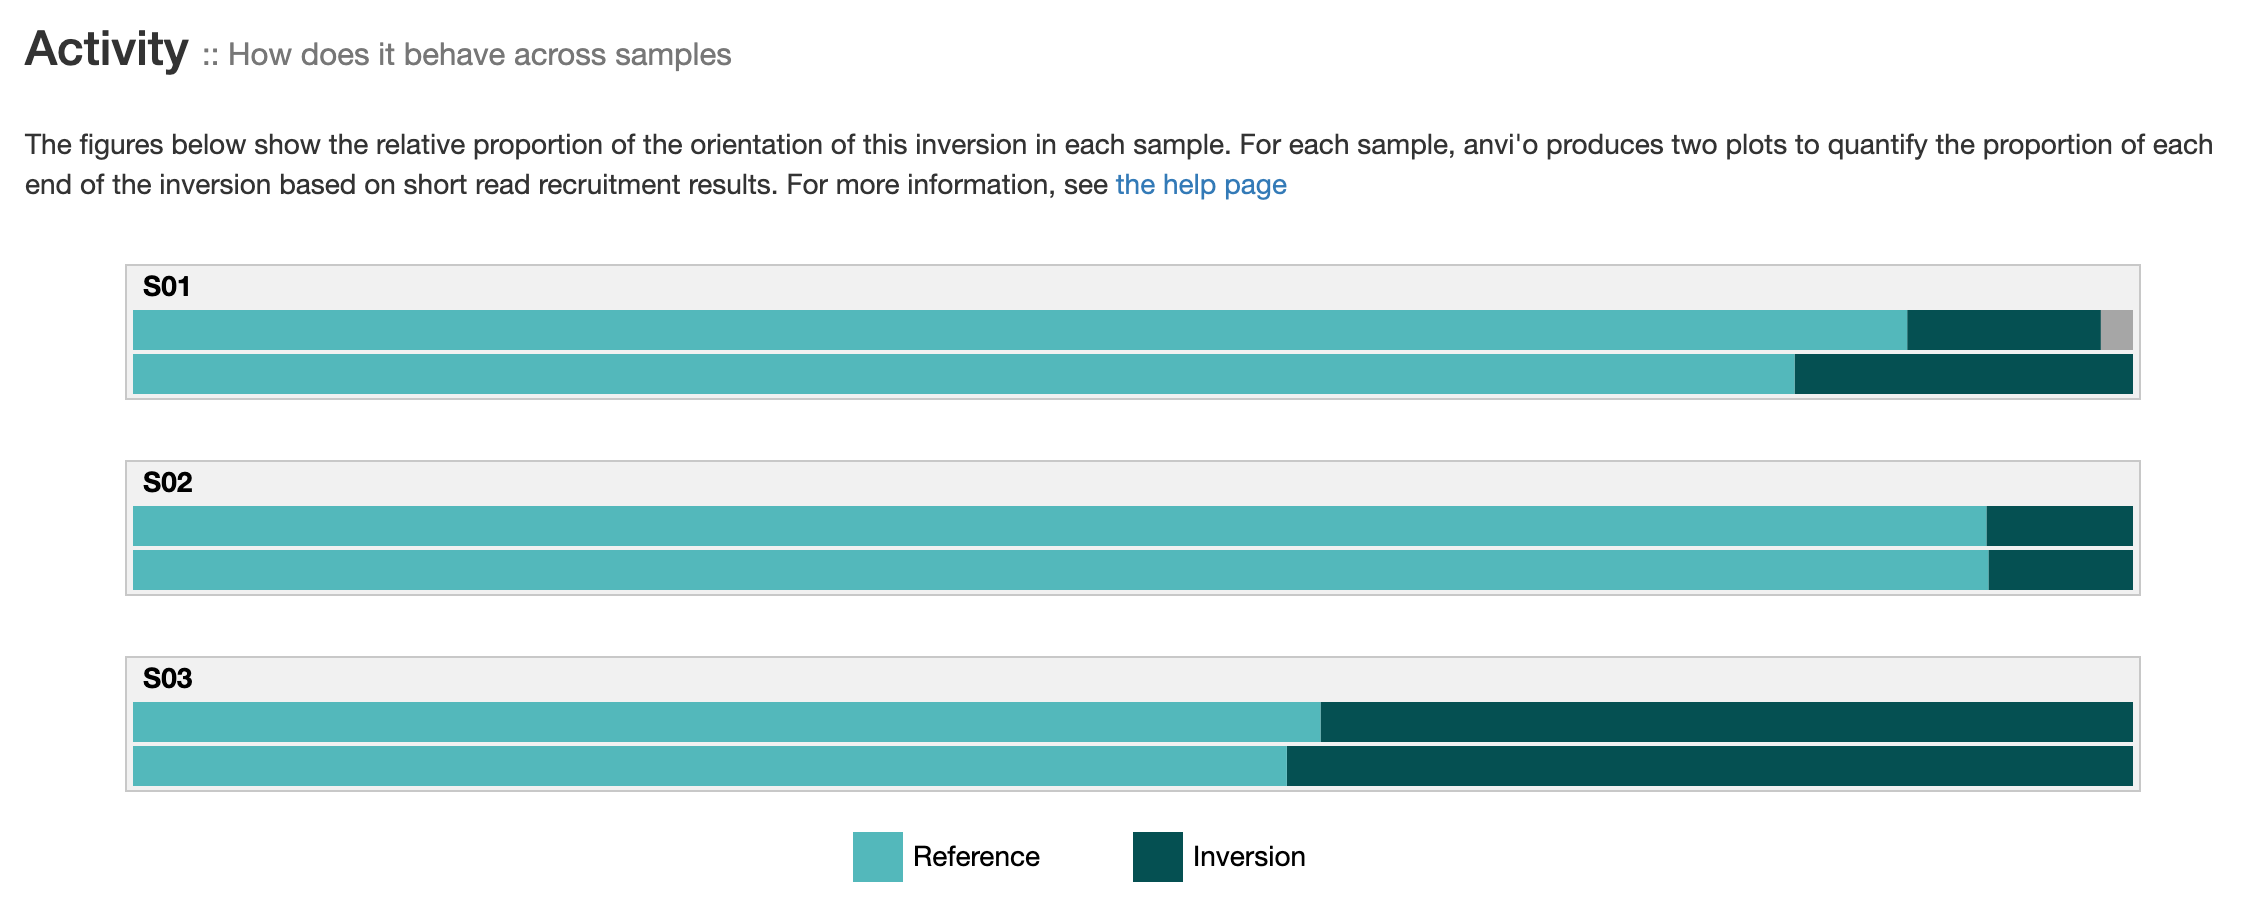
If you provided short-reads to the analysis, you can see barplots representing the inversion’s activity. As explained in the activity section, anvi’o compute the activity on each end of an inversion, which explains the two barplots per sample. “Reference” correspond to the relative proportion of short-read matching to an inversion’s orientation similar to your reference sequence. And “Inversion” correspond to the relative proportion of short-reads matching the reverse orientation.
The two barplots per sample should be relatively similar. It is not the case when (1) the coverage is low (fewer reads = less accurate relative proportions) or (2) there is more than one pair of inverted-repeat in this genomic site. Here is a nice example of multiple nested IRs. If you ever see this, you should consider re-running the command for that specific region with targeted search, and searching for all possible palindrome with --check-all-palindromes. Yes, anvi’o can report nested, multiple IRs inversions when you use these flags :rainbow:.
It is possible to see more colors than the two “Reference” and “Inversion”. For instance, if you have a nested multiple IRs inversions (lucky you), you should see another color (a variation of grey) indicating that more than one sequence can end up on this side of an inversions. Another reason is sequencing error. Anvi’o relies on exact matches to report “Reference” and “Inversion”, and a single read mismatch can create a third category (and therefore a third color in the barplot). If you see some red color, it means more than 4 different DNA sequence can be found at the edge of an inversions, which means that something is probably wrong and requires some manual inspection (or you should collect your Nobel prize).
General information
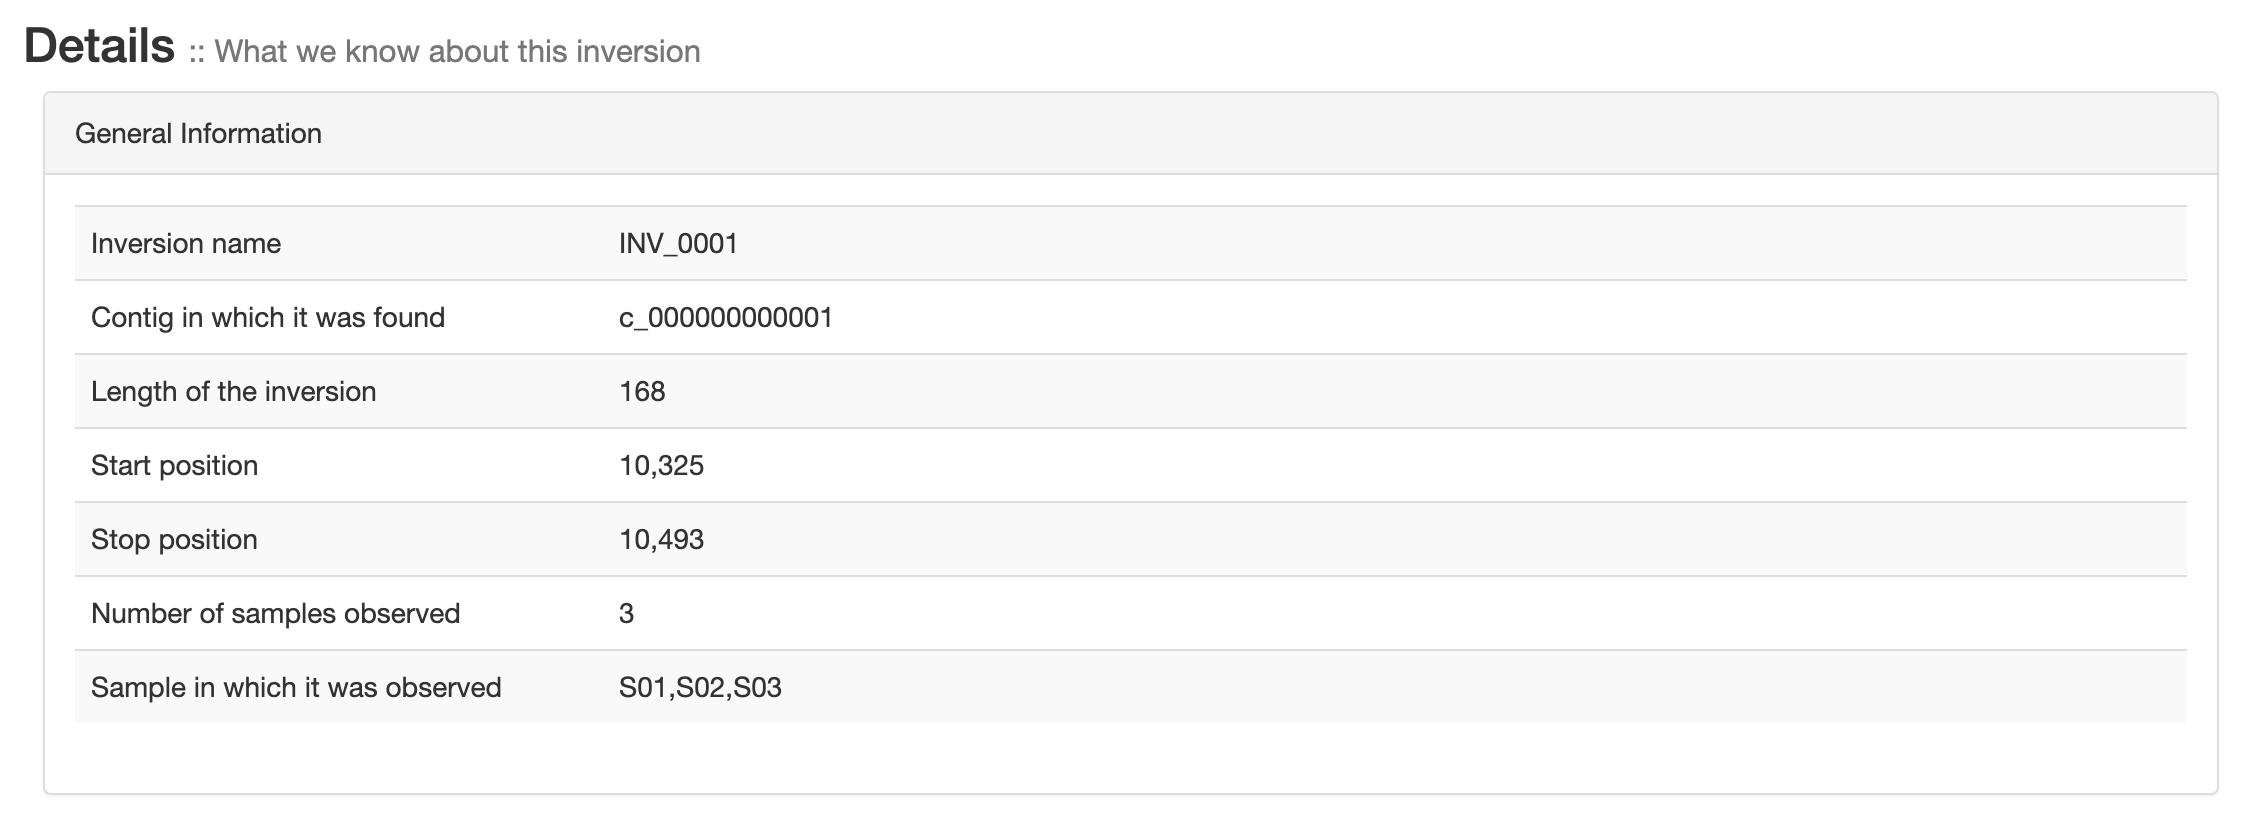
General information about each inversions like contig, position, length and the sample in which it was found.
Inverted repeats and motifs
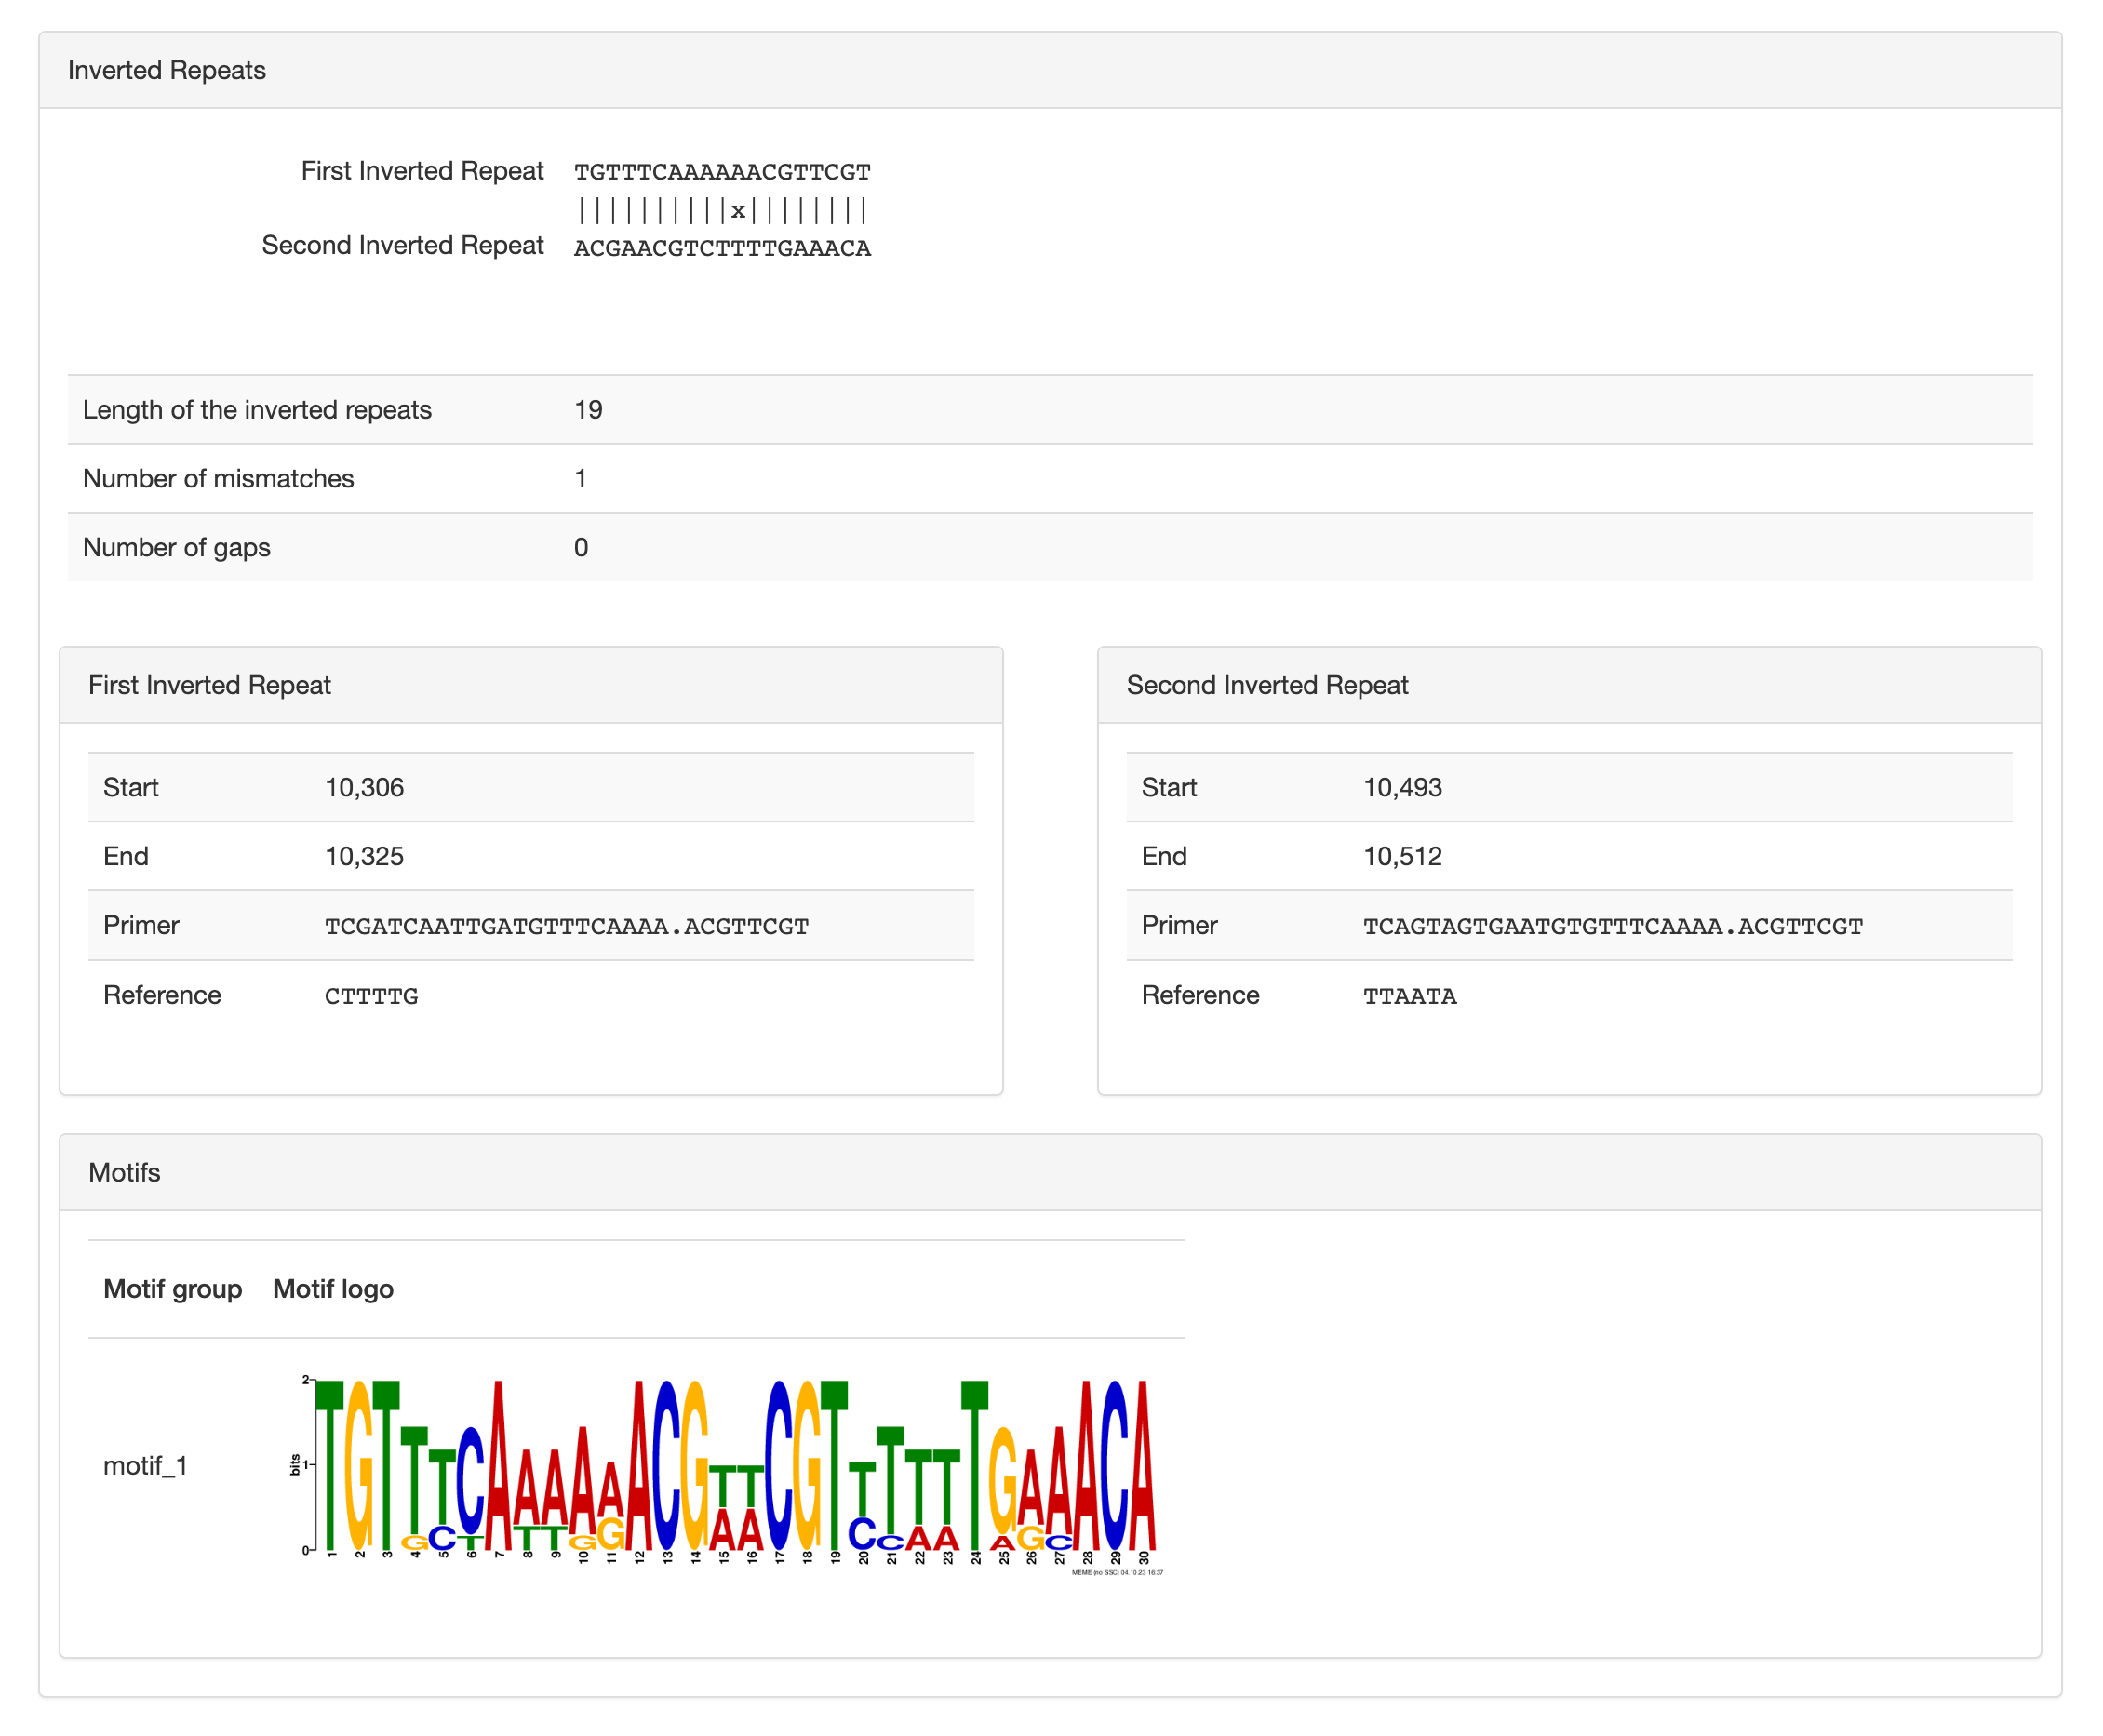
Here you can see the two inverted-repeats, their alignment, length and position. You can also see the “primer” sequence used to search short-read to report the activity, or relative proportion of an inversion’s orientation per sample.
And finally you can see the palindromic motif likely recognized by a site-specific recombinase which carries out such inversion. The same motif can occur in multiple inversions, which suggest that a unique site-specific recombinase is responsible for a set of inversions. Typically there is only one motif per inversion, but we don’t control biology so it is possible that more than one motif are reported.
Other outputs
anvi-report-inversions create an output directory with the following structure (if you have not use the --skip-[..] flags):
INVERSIONS-OUTPUT/
├── ALL-STRETCHES-CONSIDERED.txt
├── INVERSION-ACTIVITY.txt
├── INVERSIONS-CONSENSUS.txt
├── PER_INV
│   ├── ALL_INVERSIONS
│   │   ├── MEME
│   │   │   ├── logo1.eps
│   │   │   ├── [...]
│   │   │   └── meme.xml
│   │   ├── inverted_repeats.fasta
│   │   └── run-MEME.log
│   ├── INV_0001
│   │   ├── MEME
│   │   │   ├── logo1.eps
│   │   │   ├── [...]
│   │   │   └── meme.xml
│   │   ├── SURROUNDING-FUNCTIONS.txt
│   │   ├── SURROUNDING-GENES.txt
│   │   ├── inverted_repeats.fasta
│   │   └── run-MEME.log
│   └── INV_0002
│       ├── MEME
│       │   ├── logo1.eps
│       │   ├── [...]
│       │   └── meme.xml
│       ├── SURROUNDING-FUNCTIONS.txt
│       ├── SURROUNDING-GENES.txt
│       ├── inverted_repeats.fasta
│       └── run-MEME.log
├── PER_SAMPLE
│   ├── INVERSIONS-IN-S01.txt
│   ├── INVERSIONS-IN-S02.txt
│   └── INVERSIONS-IN-S03.txt
└── index.html
For more information about each of these txt files, go check inversions-txt.
Edit this file to update this information.
Command line interface
The following is the list of parameters and their descriptions in the latest version of anvi-report-inversions.
The code that generates this web page ensures that this information is the latest available in 9-dev (eunice). Which means, in some cases the information in this section (generated automatically) might be more comprehensive or up-to-date compared to the descriptions above (written by humans).
Command line usage
Parameters and their descriptions
-P, --bams-and-profilesBAMS-AND-PROFILES-FILE- A four-column TAB-delimited flat text file. The header line must contain these columns: 'name', 'contigs_db_path', 'profile_db_path', and 'bam_file_path'. See the profiles-and-bams.txt artifact for the details of the file.
--pre-computed-inversionsINVERSIONS-FILE- A TAB-delimited file that lists sample-specific or consensus inversions identified by the program `anvi-report-inversions`.
-l, --min-palindrome-lengthINT- The minimum palindrome length. Default:
10 -m, --max-num-mismatchesINT- The maximum number of mismatches allowed. Default:
0 -d, --min-distanceINT- The minimum distance between palindromic sequences (this parameter is essentially asking for the number of `x` in the sequence `ATCGxxxCGAT`). A value of 0 means that the algorithm will find all palindromes whether they are 'in-place' palindromes or distant palindromes. The default value is 50 ncl. Default:
50 --min-mismatch-distance-to-first-baseINT- This parameter allows you to trim the palindrome when one or more mismatches are n nucleotides away from a palindrome's start or stop. By default, this flag is set to 1, which means anvi'o will trim palindromes with a mismatch that are occuring on the second or n-1 position. Here is an example palindrome `MMMMMM(X)M` where `M` are the matching nucleotides and `X` is a mismatch. By default, anvi'o will only report the first six matches: `MMMMMMM`. The rationale behind this parameter is that when searching for palindromes with mismatches, the algorithm will extend the palindrome length as much as possible, often wrongly including mismatches which are outside of the true palindrome. Default:
1 --palindrome-search-algorithmPALINDROME_SEARCH_ALGORITHM- There are two algorithms for calculating palindromes: 'BLAST' and 'numba'. By default, anvi'o will dynamically optimize your search for speed and will use numba when a given sequence is shorter than 5,000 nucleotides or will use BLAST otherwise. However, you can use this parameter to ask anvi'o to use either of these methods explicitly to search for palindromes. You can choose from the options 'BLAST' or 'numba'. Please note that the results from the two approaches may differ. Choices:
BLASTnumba
--check-all-palindromes- In a given 'stretch' anvi'o has identified as a region of interest due to the coverage of FWD/FWD and REV/REV reads (see KEY ALGORITHMIC COMPONENT 01), there may be multiple palindromic sequences. By default, anvi'o will stop its search as soon as it finds evidence among short reads in the BAM file that suggests a given palindrome represents an active inversion, WITHOUT testing any of the remaining palindromes in the same region. While this strategy is extremely efficient as it will not go through all reads over and over again for each palindrome, it will miss if there are multiple inversions in a single stretch, which is extremely unlikely. But using this this you can instruct anvi'o to test ALL palindromes in a stretch. We understand -- we are unreasonable people, too.
--process-only-inverted-reads- At one point, anvi'o will have all the regions of interest in contigs that include palindromes that look promising. At that point, it will access to short reads in the BAM file to determine which palindromes in fact represent active inversions by searching for unique constructs that can only occur when a genomic region did funny things. One option is to search for such reads that are evidence of inversion activity among paired-end reads that are in FWD/FWD or REV/REV orientation. Which is defined by the fetch-filter 'inversions'. However, this may be too limiting as there may be paired-end reads that are too downstream or too upstream to the region of interest, and thus mapping FWD/REV or REV/FWD orientation just like every other non-rebellious paired end read, YET including one of the constructs. Thus, searching all reads may in fact help the identification of more inversions (especially those that are covered less), with only an added disadvantage of compute time, which should be negligible in almost all instances (since anvi'o at this stage is only focusing on very specific regions of genomes). But this parameter is here in case you insist on only using inverted paired-end reads and assert your authority. You do you and turn on the flag, you rebellious scientist who will likely miss a lot of additional inversions like a boss.
-T, --num-threadsNUM_THREADS- Maximum number of threads to use for multithreading whenever possible. Very conservatively, the default is 1, unless the environmental variable `ANVIO_THREADS` sets another positive integer. If you use this parameter, it will override `ANVIO_THREADS`. It is a good idea to not exceed the number of CPUs / cores on your system. Plus, please be careful with this option if you are running your commands on a SGE -- if you are clusterizing your runs, and asking for multiple threads to use, you may deplete your resources very fast. Default:
1 --oligo-primer-base-lengthINT- Calculating inversion ratios require anvi'o to 'design' an in silico primer based on palindromes associated with inversions and the upstream/downstream genomic context to search for short reads in raw sequencing datato find the ratio of inversion activity per sample. This variable is to control how much of the palindrome for a given inversion should be used to build a primer to search for short reads. The longer it is, the more specific the primers will be to survey short reads. But if if it is too long, then there will not be enough reads to 'keep' depending on the minimum short read length of the sequencing. The default value will probably good for the vast majority of cases. Default:
12 --skip-compute-inversion-activity- This flag will help you skip computing inversion activity, which is an extremely costly step, even if your `bams-and-profiles-txt` contains `r1` and `r2` entries. It may be a good idea to first run the workflow without computing activity, take a look at the CONSENSUS file to make sure everything looks alright, and then run the workflow without this flag.
--end-primer-search-after-x-hitsEND_PRIMER_SEARCH_AFTER_X_HITS- For very large datasets, primer search can take a very long time. By setting a small integer here, you can ask anvi'o to stop searching primers after a few hits. Once the total number of primer hits reach to number for a given sample, anvi'o will stop searching further and continue with the next sample. This flag is only good for testing, since it will prematurely end the search without testing all primers
--min-frequency-to-reportMIN_FREQUENCY_TO_REPORT- By default, anvi'o will only report primers supported by more than one read from the `r1` and `r2` entry in your `bams-and-profiles-txt`. The reason for this filtering is sequencing errors, which can create very low frequency entries in the activity report. Use this flag to change that minimum threshold. Default:
1
--skip-recovering-genomic-context- Of course you can skip this step because why should anyone have nice things.
--num-genes-to-consider-in-contextINT- With this parameter you can adjust the number of genes anvi'o should consider to characterize the genomic context surrounding inversions. If you set nothing here, anvi'o will go 3 genes upstream from the first palindrome of the inversion and 3 genes downstream from the second. If there are not enough genes in the contig given the position of either of the palindromes, anvio' will report whatever it can. Default:
3 --gene-callerGENE-CALLER- The gene caller to show gene calls from.
--skip-search-for-motifs- Skip the search for conserved motifs in inverted repeats.
--num-of-motifsINT- By default anvi'o will search for as many motifs as inversions. It can be time consuming if you have a lot of inversions. You can use that flag to search for less motifs.
--verbose- Be verbose, print more messages whenever possible. You may regret this.
--target-contigCONTIG_NAME- Contig name of interest.
--target-region-startNUCLEOTIDE_POSITION- The start position of the region of interest.
--target-region-endNUCLEOTIDE_POSITION- The end position of the region of interest.
-o, --output-dirDIR_PATH- Directory path for output files
Additional Resources
Are you aware of resources that may help users better understand the utility of this program? Please feel free to edit this file on GitHub. If you are not sure how to do that, find the __resources__ tag in this file to see an example.