The anvi'o 'contigs' workflow
Table of Contents
From FASTA files to annotated anvi'o contigs databases
This workflow is useful for converting a bunch of genomes into an anvi'o-compatible format. It generates contigs databases from each input FASTA file, and subsequently runs a variety of annotation programs of your choice to populate these databases with some useful information for your downstream work (i.e. functions, single-copy-core genes, taxonomy, etc).
🔙 To the main page of anvi’o programs and artifacts.
Authors
Artifacts accepted
The contigs can typically be initiated with the following artifacts:
Artifacts produced
The contigs typically produce the following anvi’o artifacts:
Third party programs
This is a list of programs that may be used by the contigs workflow depending on the user settings in the workflow-config  :
- pyrodigal-gv (Gene calling)
- HMMER (HMM search)
- krakenuniq (Gene taxonomy)
- centrifuge (Gene taxonomy)
- DIAMOND (Sequence search against various databases)
An anvi’o installation that follows the recommendations on the installation page will include all these programs. But please consider your settings, and cite these additional tools from your methods sections.
Workflow description and usage
This workflow is extremely useful if you have one or more fasta files that describe one or more contig sequences for your genomes or assembled metagenomes, and all you want to turn them into contigs-db files.
If you have not yet run anvi’o programs anvi-setup-ncbi-cogs and anvi-setup-scg-taxonomy on your system yet, you will get a cryptic error from this workflow if you run it with the default workflow-config. You can avoid this by first running these two anvi’o programs to setup the necessary databases (which is done only once for every anvi’o installation), or set the rules for COG functions and/or SCG taxonomy to run=false explicitly.
To start things going with this workflow, first ask anvi’o to give you a default workflow-config file for the contigs workflow:
anvi-run-workflow -w contigs \
                  --get-default-config config-contigs-default.json
This will generate a file in your work directory called config-contigs-default.json. You should investigate its contents, and familiarize youself with it. It should look something like this, but much longer:
and you could examine its content to find out all possible options to tweak. We included a much simpler config file, config-contigs.json, in the mock data package for the sake of demonstrating how the contigs workflow works:
{
    "workflow_name": "contigs",
    "config_version": "2",
    "fasta_txt": "fasta.txt",
    "output_dirs": {
        "FASTA_DIR": "01_FASTA",
        "CONTIGS_DIR": "02_CONTIGS",
        "LOGS_DIR": "00_LOGS"
    }
}
The only mandatory thing you need to do is to (1) manually create a fasta-txt file to describe the name and location of each FASTA file you wish to work with, and (2) make sure the fasta_txt variable in your workflow-config point to the location of your fasta-txt.
To see if everything looks alright, you can simply run the following command, which should generate a ‘workflow graph’ for you, given your config file parameters and input files:
anvi-run-workflow -w contigs \
                  -c config-contigs.json \
                  --save-workflow-graph
For the example config file shown above, this command will generate something similar to this:
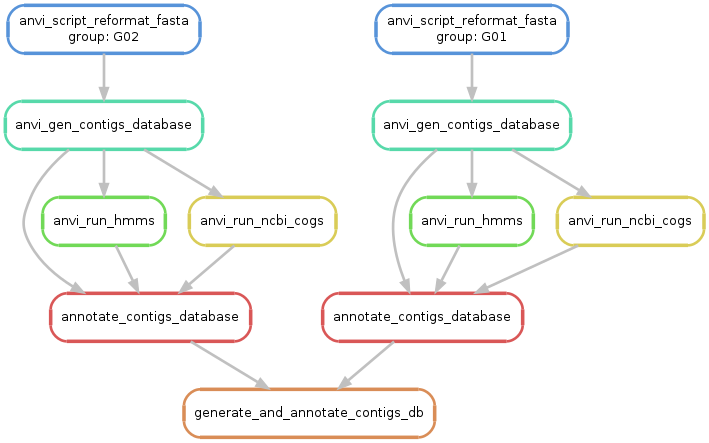
Please note that the generation of this workflow graph requires the usage of a program called dot. If you are using MAC OSX, you can use dot by installing graphviz through brew or conda.
If everything looks alright, you can run this workflow the following way:
anvi-run-workflow -w contigs \
                  -c config-contigs.json
If everything goes smoothly, you should see happy messages flowing on your screen, and at the end of it all you should see your contigs databases are generated and annotated properly. At the end of this process, you will have all your contigs-db files in the 02_CONTIGS directory (as per the instructions in the config file, which you can change). You can use the program anvi-display-contigs-stats on one of them to see if everything makes sense.
Workflow logs will be under 00_LOGS/contigs by default. Rule logs are organized by rule name, and the contigs workflow writes a tab-delimited manifest at 00_LOGS/contigs/contigs-workflow-manifest.tsv that points to each job’s log and records whether it succeeded or failed.
Predicting protein structures
The contigs workflow can also predict the structures of the genes in each contigs-db, and store them in a structure-db using anvi-gen-structure-database. This step is off by default. To turn it on, set run to true for the rule anvi_gen_structure_database in your workflow-config. Every parameter of the prediction (including the --engine, which can be modeller or colabfold) lives under this rule:
"anvi_gen_structure_database": {
    "run": true,
    "threads": 4,
    "--engine": "colabfold",
    "--colabfold-conda-env": "colabfold",
    "--colabfold-db": "/path/to/colabfold_db"
}
The workflow writes one structure-db per FASTA file into 03_STRUCTURE, e.g., 03_STRUCTURE/SAMPLE_01-STRUCTURE.db. The prediction does not hold up the rest of the workflow: it only needs the contigs-db, and annotating the contigs-db afterwards will not trigger a new prediction.
Once a structure-db exists, the workflow never touches it again, even if you change the structure parameters in your workflow-config or the genes of interest of that contigs-db: predicting structures can take days, and the workflow will not delete them. Anvi’o lists these structure-db files every time you run the workflow. To predict the structures of a contigs-db again, move or remove its structure-db first. To only add genes to it, you can use anvi-update-structure-database. The workflow writes each structure-db under a temporary name (e.g., 03_STRUCTURE/SAMPLE_01-STRUCTURE-INCOMPLETE.db) and only renames it once it is complete, so a job that failed or was killed (for instance, by your cluster’s time limit) does not leave behind an unfinished structure-db under its final name. If you stop the workflow yourself with Ctrl-C, please check 03_STRUCTURE before running it again.
The workflow also makes sure each existing structure-db was made from the contigs-db it belongs to, and stops if it was not (for instance, if you made a contigs-db again), so you can move or remove the old structure-db.
With MODELLER, a structure-db may contain no structures at all, when MODELLER does not find a good enough template for any of the genes of interest. This is not an error: the structure-db still records the genes anvi’o tried.
Choosing genes
By default, anvi’o predicts a structure for every gene of every contigs-db, and warns you when it is about to do so. A single genome has thousands of genes, so this can take a very long time. To limit the prediction to some genes, add a structure_genes_of_interest column to your fasta-txt that points to a genes-of-interest-txt for each FASTA file:
| name | path | structure_genes_of_interest |
|---|---|---|
| SAMPLE_01 | path/to/sample_01.fa | genes_01.txt |
| SAMPLE_02 | path/to/sample_02.fa |
Here, anvi’o predicts structures for the genes listed in genes_01.txt for SAMPLE_01, and for every gene of SAMPLE_02.
Since gene caller ids only exist once a contigs-db is built, you can first run the workflow without structure prediction, pick your genes, add the column to your fasta-txt, turn on anvi_gen_structure_database, and then run the workflow again: anvi’o will only run the missing structure steps.
Splitting ColabFold into CPU and GPU steps
ColabFold generates multiple sequence alignments (MSA) on the CPU, then predicts structures on the GPU. With a local ColabFold database (--colabfold-db), you can set split_msa_and_predict to true for anvi_gen_structure_database to run these as two separate jobs: colabfold_msa (with --only-msa) and colabfold_predict (with --only-predict). This way, a cluster can run each one on the appropriate node. Each of these two rules has its own threads, and takes every other parameter from anvi_gen_structure_database. The MSAs go into a temporary 03_STRUCTURE/SAMPLE_01-COLABFOLD-MSA directory that the workflow removes once the structure-db is built.
GPU resources
The rules that predict structures with ColabFold (colabfold_predict, and anvi_gen_structure_database when --engine is colabfold) declare a GPU through the snakemake resource gpu=1. MODELLER and colabfold_msa declare gpu=0. You can change this number with the gpu parameter of anvi_gen_structure_database and colabfold_predict.
It is up to you to map this resource onto your scheduler. On a single machine with one GPU, you can make sure that only one prediction runs at a time with --additional-params --resources gpu=1 nodes=N, where N is the total number of threads for your workflow (anvi’o sets nodes itself only when you do not pass your own --resources).
On a cluster, you can pass the number of GPUs of each job to your submission command with {resources.gpu} in the snakemake --cluster string. Since only the structure rules declare a gpu resource, you also need to give every other rule a default value with --default-resources gpu=0. Otherwise snakemake cannot fill in {resources.gpu} for them and stops before submitting any job. Your submission command must then treat 0 as “no GPU”.
If your cluster has a dedicated partition for GPU jobs, you can use the same mechanism with a custom partition resource: a default for every rule with --default-resources, and a different value for the rules that need a GPU with --set-resources. Here is an example with SLURM’s sbatch, where cpu_part and gpu_part are the names of your partitions:
anvi-run-workflow -w contigs \
                  -c config-contigs.json \
                  --additional-params \
                      --cluster "sbatch --cpus-per-task={threads} --gres=gpu:{resources.gpu} --partition={resources.partition}" \
                      --default-resources gpu=0 partition=cpu_part \
                      --set-resources colabfold_predict:partition=gpu_part \
                      --jobs 20 \
                      --resources nodes=64 \
                      --latency-wait 100
Only list the rules that actually use a GPU under --set-resources: colabfold_predict when split_msa_and_predict is true, or anvi_gen_structure_database when it runs ColabFold in a single step. With MODELLER, anvi_gen_structure_database belongs on the CPU partition. You can also add gpu=N to --resources to limit the number of GPU jobs submitted at the same time.
Edit this file to update this information.